The Cost of Thinking Fast? Testing Jev with CityMaker
A new way of modeling the learning process - Bo Wen
At Enkira, we are teaching AI agents the logic of commerce. A human salesperson can often tell at a glance what a buyer wants, which catalog item matches, and whether a proposed sale adds something the buyer never requested. In our work, general-purpose LLMs can need several reasoning steps to get these seemingly simple judgments right. When TypeSafe introduced Jev as a fast “System One” decision model, we designed an experiment using a small, fixed set of real buying-and-selling interactions to test its business judgments.
We gave Jev three tasks within those transactions: pick the right item from a short catalog list, identify the buyer's intent from a message, and audit a draft sale against the conversation and catalog. We kept the underlying interactions fixed while varying how we described choices and judging criteria. Jev picked the expected item in 22 of 27 cases. Clarifying intent labels raised strict intent accuracy from 91 of 105 to 94 of 105 messages.
The most instructive result came from checking draft sales. Across nine interactions, we tested nine correct drafts and 53 incorrect versions, including drafts with modified details or unsupported additions. A strict rubric caught all 53 incorrect drafts, yet treated all nine correct drafts as doubtful. The reason was concrete: each draft displayed the catalog's standard listed price, whereas the rubric instructed the model to reject amounts not explicitly stated by the buyer. Jev treated that reference price as an unapproved extra charge, following the rule literally.
We clarified the business rule: the listed price is catalog information; an additional charge requires explicit support from the buyer's request. With that change, Jev still flagged 53 of 53 incorrect drafts while confidently accepting 4 of 9 correct ones. Adding worked examples to the ambiguous rubric had not helped; explaining the semantic meaning of transaction data was the single most effective change. Five correct drafts still required review, and the test set and labels remain small and provisional.
This shift shows that Jev applies criteria literally: prompt wording directly shapes its decision logic. To test whether the structured output format alone explained its performance, we replayed the same cases using an open-source decoding project. At the tested version, it wrapped stock Qwen2.5-Instruct weights and was not a separately trained decision model. We also built a local variant that presented every choice to the model and scored complete answers, before testing a larger 7B model.
Under corresponding settings, the 7B model picked 17 of 27 items (Jev: 22 of 27) and classified 73 of 105 buyer messages (Jev: 94 of 105). On draft checking, it confidently accepted 6 of 9 correct drafts but missed 11 of 53 incorrect ones; in comparison, Jev accepted 4 of 9 correct drafts and caught all 53 incorrect ones. The smaller model performed worse across item and intent selection and failed to distinguish good drafts from bad ones. Output formatting alone did not replicate Jev's performance. TypeSafe notes that Jev is post-trained for calibrated decisions, which appears to be the primary driver of its improved performance.
In our evaluation, Jev delivered fast, reliable judgments when business facts and rules were explicit. When facts are missing or a rule is ambiguous, the case must be routed to a slower step that searches, calculates, or requests clarification. This highlights the System One / System Two division we care about: fast decisions within defined boundaries, and deliberate reasoning when those boundaries are crossed.
Our collaborator Derek Wang ran a separate test in CityMaker, a beautiful 2048-style puzzle game. To our surprise, Jev frequently chose directions that left the board unchanged when given only basic game rules as instructions. When the game engine pre-calculated each move's consequences, Jev's score rose from 1,312 to 5,116. This echoes our finding: selecting a good outcome is easy when choices are pre-evaluated, but determining how to reach that outcome requires reasoning. Knowing the rules of a game does not mean knowing how to play well. In TypeSafe's Doom demo, for instance, the strategy appears to be hardcoded into the decision tree.
Humans use deliberate thought to derive strategies from rules—a process typically described as decomposing a complex problem into smaller, solvable subproblems. This suggests we could handcraft an explainable decision network using an LLM to map out the decision tree, and then execute it using System One models like Jev. This offers a promising direction for building agents that learn business logic and adapt as conditions change.
The following is an English translation of Derek Wang's article, originally published on WeChat. The experiment and conclusions in the translated article are his own. Experiment code.
Original article cover: “The Cost of Thinking Fast? Testing Jev with CityMaker.”
Jev has been everywhere lately. In a field dominated by large-model giants, it feels like a breath of fresh air: a viable alternative to simply climbing benchmark leaderboards.
Its developer, TypeSafe, calls it a “System One Model.” The name stems from Daniel Kahneman's Thinking, Fast and Slow, which defines System One as fast, automatic, and intuitive pattern recognition—like recognizing a familiar face at a glance. System Two, by contrast, is slow and effortful, handling reasoning, calculation, and deliberation (such as multiplying 17 by 24 in your head). TypeSafe focuses on System One. The company reports end-to-end latency of 70–500 milliseconds and substantial speed and cost advantages over frontier LLMs: tens to hundreds of times faster at near-zero cost.
I wanted to test it myself. I connected CityMaker, a 2048-style game I created, to its game engine and ran a series of experiments.
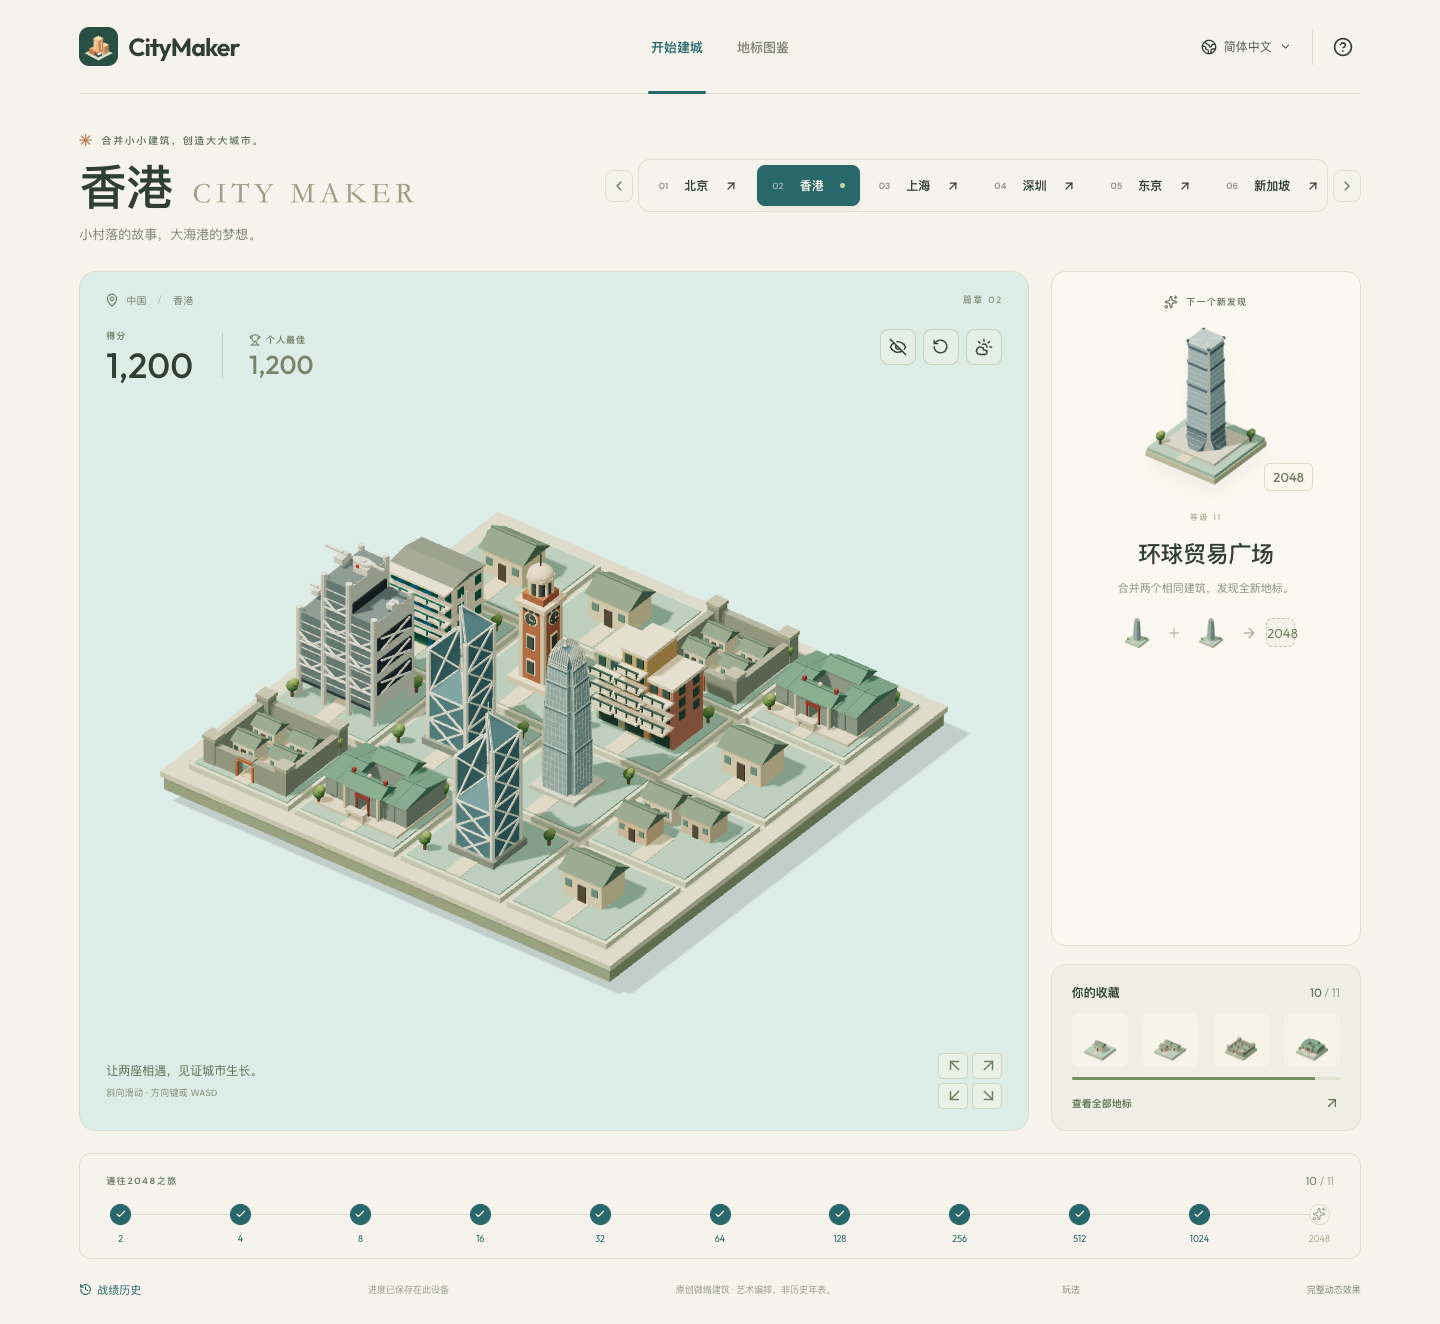
CityMaker game interface, from the original article.
Experimental setup
- Game: CityMaker, similar to 2048.
- Protocol: Direct calls, with the board sent as a two-dimensional array alongside the rules and objective.
- Seeds: 1000–1004, with a 400-move budget.
- Baselines:
random,random-legal,priority-left-up, andexpectimax-d2. - Additional comparison: One game on seed 1000 with GPT-5.6 Luna and Terra.
I had high hopes. Jev would select directions every few hundred milliseconds, tiles would slide and merge across the board, and the city would grow toward a major landmark. If successful, it would prove that a model designed for fast decisions could also make smart ones.
That is not what happened. Although Jev returned decisions in ~350 milliseconds, it frequently chose moves that left the board completely unchanged. Its median score in the baseline group was only slightly above random play. In a test evaluating move legality, its accuracy fell below a naive baseline that always answered “yes.”
This evaluation raised fundamental doubts about Jev's capabilities. Its weaknesses spanned rule comprehension, board-state evaluation, and action selection—all core components of intelligence.
1. Why use CityMaker to test “fast thinking”?
CityMaker's rules are simple: move in one of four directions, merge matching numbers, spawn a new tile after each valid move, and end the game when no valid moves remain.
Although structured as a strategy game, players often rely on quick visual heuristics rather than deep multi-step lookahead. A quick glance reveals:
- Move left and those two 2s will merge.
- Move up and this column will get stuck.
- Move right and there will be more empty spaces.
This relies on fast inference and pattern recognition. You don't need to compute several steps ahead; you just need to recognize which directions are open, which are blocked, and which create space. Jev is positioned specifically as a System One model: fast, intuitive pattern matching.
That makes CityMaker an ideal test: how effectively does a self-described System One model handle fast inference and pattern recognition?
2. Paired by seed: Jev can play, but it did not beat the simplest strategy
I sent the board state directly to the model as a two-dimensional array and benchmarked its performance seed-by-seed against several baseline algorithms.
Seeds. Each game used a fixed seed (1000–1004). A given seed determines the initial board and subsequent tile spawn sequences, ensuring identical starting conditions across strategies. However, board states diverge as strategies choose different moves.
Baselines. All opponents listed below are non-LLM, rule-based algorithms:
randomchooses uniformly across all four directions, including invalid moves.random-legalchooses randomly among valid moves that change the board state. Comparing it withrandomhelps isolate board-reading failures from poor action selection.priority-left-upattempts left, up, right, then down, selecting the first valid move. It uses no learning or lookahead, representing the simplest deterministic strategy.expectimax-d2performs a 2-ply search and serves as an upper-bound reference.- Jev (direct protocol) receives the board state and rules, selecting a direction directly.
Invalid-move rate measures the proportion of moves that leave the board unchanged. An invalid move spawns no tile and costs no points, but wastes a turn. Since recognizing valid directions is a basic pattern-recognition task, this rate should ideally be near zero. random wastes 11.8% of moves, whereas random-legal and priority-left-up waste 0%. Because each strategy experiences different board trajectories, this metric should be interpreted within each run rather than used in isolation.
| Strategy | Median score | Largest tile | Invalid moves |
|---|---|---|---|
random |
1,076 | 128 | 11.8% |
random-legal |
1,008 | 64 | 0% |
| Jev, direct protocol | 1,188 | 128 | 19.5% |
priority-left-up |
2,360 | 256 | 0% |
expectimax-d2† |
13,232 | 1,024 | — |
† expectimax-d2 is a separate reference result over 200 seeds, not one of the five-seed paired runs.
Jev outperformed random on 4 of 5 seeds and random-legal on 3 of 5 seeds, but lost to priority-left-up on all 5 seeds. While Jev wasn't choosing completely at random, its advantage over random play was minimal. It never beat the simple heuristic of "try left, then up, then right, then down." The 2-ply expectimax search achieved a median score of 13,232 across 200 seeds (compared to Jev's 1,188 across 5 seeds); while these use different sample sizes, the gap illustrates the difference between fast intuition and search.
The invalid-move rate is even more revealing. Random play wasted 11.8% of moves, whereas Jev wasted 15.3%–21.6% across runs—worse than random guessing. On the basic task of identifying moves that alter the board, Jev demonstrated no meaningful edge over random selection. For a modern AI model, basic board-state recognition should be a baseline capability.
3. A prompt ladder: explaining the mechanics helped; teaching a strategy hurt
To test whether Jev's poor performance stemmed from rule ambiguity, I tested four prompt variations, each progressively adding structure:
bare: Minimal rules: a 4×4 board, sliding/merging mechanics, tile spawning rules, wasted turn penalties, and game-over conditions. No strategy or directional advice was provided.rules: Detailed mechanics: tile spawn probabilities (90% for 2, 10% for 4); five handwritten merge examples (e.g.,[2,2,2,0]sliding left becomes[4,2,0,0], scoring 4 points); and an explicit rule stating that invalid moves are strictly inferior to valid choices.tips: Adds heuristic criteria (presented as balancing factors rather than strict rules): prioritize open space, eliminate invalid moves first, merge large tiles, keep high-value tiles adjacent, and maintain the largest tile in a corner with decreasing values radiating outward.coached: Replaces balanced heuristics with a single rigid strategy: lock the largest tile in a corner, maintain descending order along its row/column, and never move it out of the corner.
The game rules and board states remained identical across runs; only the guiding prompts changed. Ironically, the coached prompt never specified a literal direction. However, on specific board states, "lock the largest tile in a corner" caused Jev to stubbornly pick a single direction even when it became invalid.
| Prompt | Added guidance | Median score | Largest tile | Invalid moves |
|---|---|---|---|---|
bare |
Minimal rules | 1,188 | 128 | 19.5% |
rules |
Spawn probabilities, merge examples, cost of dead moves | 1,312 | 128 | 29.7% |
tips |
Evaluation criteria | 764 | 64 | 14.2% |
coached |
Fixed “keep the largest tile in a corner” strategy | 80 | 16 | 95.5% |
rules achieved the highest performance. Adding spawn probabilities, concrete merge examples, and explicit invalid-move penalties raised the median score from 1,188 to 1,312. It was also the only prompt to beat random on every seed and defeat priority-left-up on seed 1004 (1,904 vs. 1,716). Nevertheless, its invalid-move rate rose to 29.7%—showing that higher scores did not translate to better move validation.
tips improved move validity but reduced overall score. Its invalid-move rate fell from 19.5% to 14.2% (the lowest among Jev prompt groups), indicating that instructing the model to avoid dead moves had some effect. However, its median score dropped by one-third and games ended sooner. Reducing invalid moves alone does not guarantee high scores: overly cautious legal moves can fail to merge tiles effectively.
coached resulted in catastrophic failure across all seeds. Its median invalid-move rate reached 95.5% (ranging from 48.8% to 98.2% across individual games). Four games exhausted the 400-move limit with virtually no progress; before games ended, the median count of valid moves was just 18. When instructed to "keep the largest tile in a corner," Jev blindly repeated invalid moves until the game stalled.
Across all prompt variations, a clear pattern emerged: Jev followed prompt instructions rigidly, but struggled to evaluate board states accurately.
4. Compared with conventional LLMs: thinking is an extra tool
Holding the game server and prompt fixed, I compared Jev against reasoning-capable LLMs on seed 1000:
| Strategy | Score | Largest tile | Invalid moves | Thinking tokens | Latency |
|---|---|---|---|---|---|
Luna-high, rules |
6,228* | 512 | 0.2% | 737k | 12.0s |
Luna-low, coached |
5,520 | 512 | 3.1% | 158k | 4.8s |
Luna-high, coached |
3,700 | 256 | 0.3% | 300k | 7.4s |
priority-left-up |
3,316 | 256 | 0% | — | — |
Terra-med, coached |
3,176 | 256 | 1.5% | 78k | 4.7s |
Luna-low, rules |
2,800 | 256 | 0.4% | 118k | 5.5s |
random-legal |
2,728 | 256 | 0% | — | — |
Terra-med, rules |
1,456 | 128 | 0% | 102k | 8.3s |
Jev, direct rules |
1,312 | 128 | 26.8% | — | 0.35s |
random |
404 | 32 | 18.3% | — | — |
*Luna-high with rules was still active at the 400-move limit, so 6,228 is a censored score. Its final score would have been higher; this row should not be ranked directly against completed games.
Key takeaways:
Reasoning LLMs accurately evaluated board states. Models with thinking capabilities made invalid moves only 0%–3.1% of the time, compared to Jev's 26.8%. Even in fast-paced tasks, simulating moves prior to acting drastically reduces wasted actions.
Prompting impacted Jev and standard LLMs differently. The "lock the tile in a corner" rule caused Jev's invalid-move rate to skyrocket to 95.5%, whereas it improved performance for Luna-low and Terra.
Deliberate reasoning adds significant value. Luna-high with rules utilized 737,000 thinking tokens and made invalid moves only 0.2% of the time by calculating board transitions prior to output. In contrast, Jev responded in ~350ms without internal chain-of-thought or simulation.
Note: These baseline LLM figures reflect single-game runs (n=1 per row). Due to variance across seeds, individual model rankings should be viewed as illustrative; however, the invalid-move gap between Jev and reasoning models is statistically pronounced.
5. Probe experiments: in CityMaker, is the missing ability “calculate” or “choose”?
To isolate Jev's specific failure modes, I ran three diagnostic probes:
Probe 1: Can Jev select optimal moves when all choices are legal?
Filtering for board states where all four move directions were valid removed move legality as a variable:
| Strategy | All-legal boards | Chose reference favorite | Average rank |
|---|---|---|---|
Jev, bare |
70 | 24.3% | 2.53 |
Jev, rules |
69 | 24.6% | 2.49 |
Luna-low, rules |
142 | 50.0% | 1.79 |
Luna-high, rules |
228 | 53.1% | 1.71 |
| Random choice | — | 25.0% | 2.50 |
The reference baseline (expectimax-d2) uses shallow search with heuristic scoring. On all-legal boards, Jev selected the reference choice 24.3%–24.6% of the time—virtually identical to random selection (25%). Jev showed no ability to distinguish superior moves among valid options.
Probe 2: Can Jev identify invalid moves?
In a standalone binary classification task on 120 static board states (60 all-legal, 60 with dead moves), I asked Jev whether each direction would change the board:
| Model | Per-direction accuracy | All four correct | Precision identifying dead moves | Recall identifying dead moves |
|---|---|---|---|---|
| Jev | 85.0% | 49.2% | 48.1% | 18.3% |
| Luna-low | 90.6% | 65.0% | 96.4% | 38.0% |
| Always answer “yes” | 85.2% | 50.0% | — | 0% |
Jev performed comparably to a dummy baseline that always answers "yes" (85.0% vs. 85.2% accuracy). When Jev flagged a move as invalid, it was correct 48.1% of the time. However, it only flagged 27 invalid moves in total (13 true positives, 14 false positives) out of 71 actual invalid directions. While a weak signal exists, the model rarely leveraged it.
Probe 3: Supplying pre-calculated move outcomes
In the preview condition, the game engine evaluated each move and passed explicit outcomes in the prompt (e.g., "left: changes board; 2 merges, +8 pts, 5 open tiles remaining").
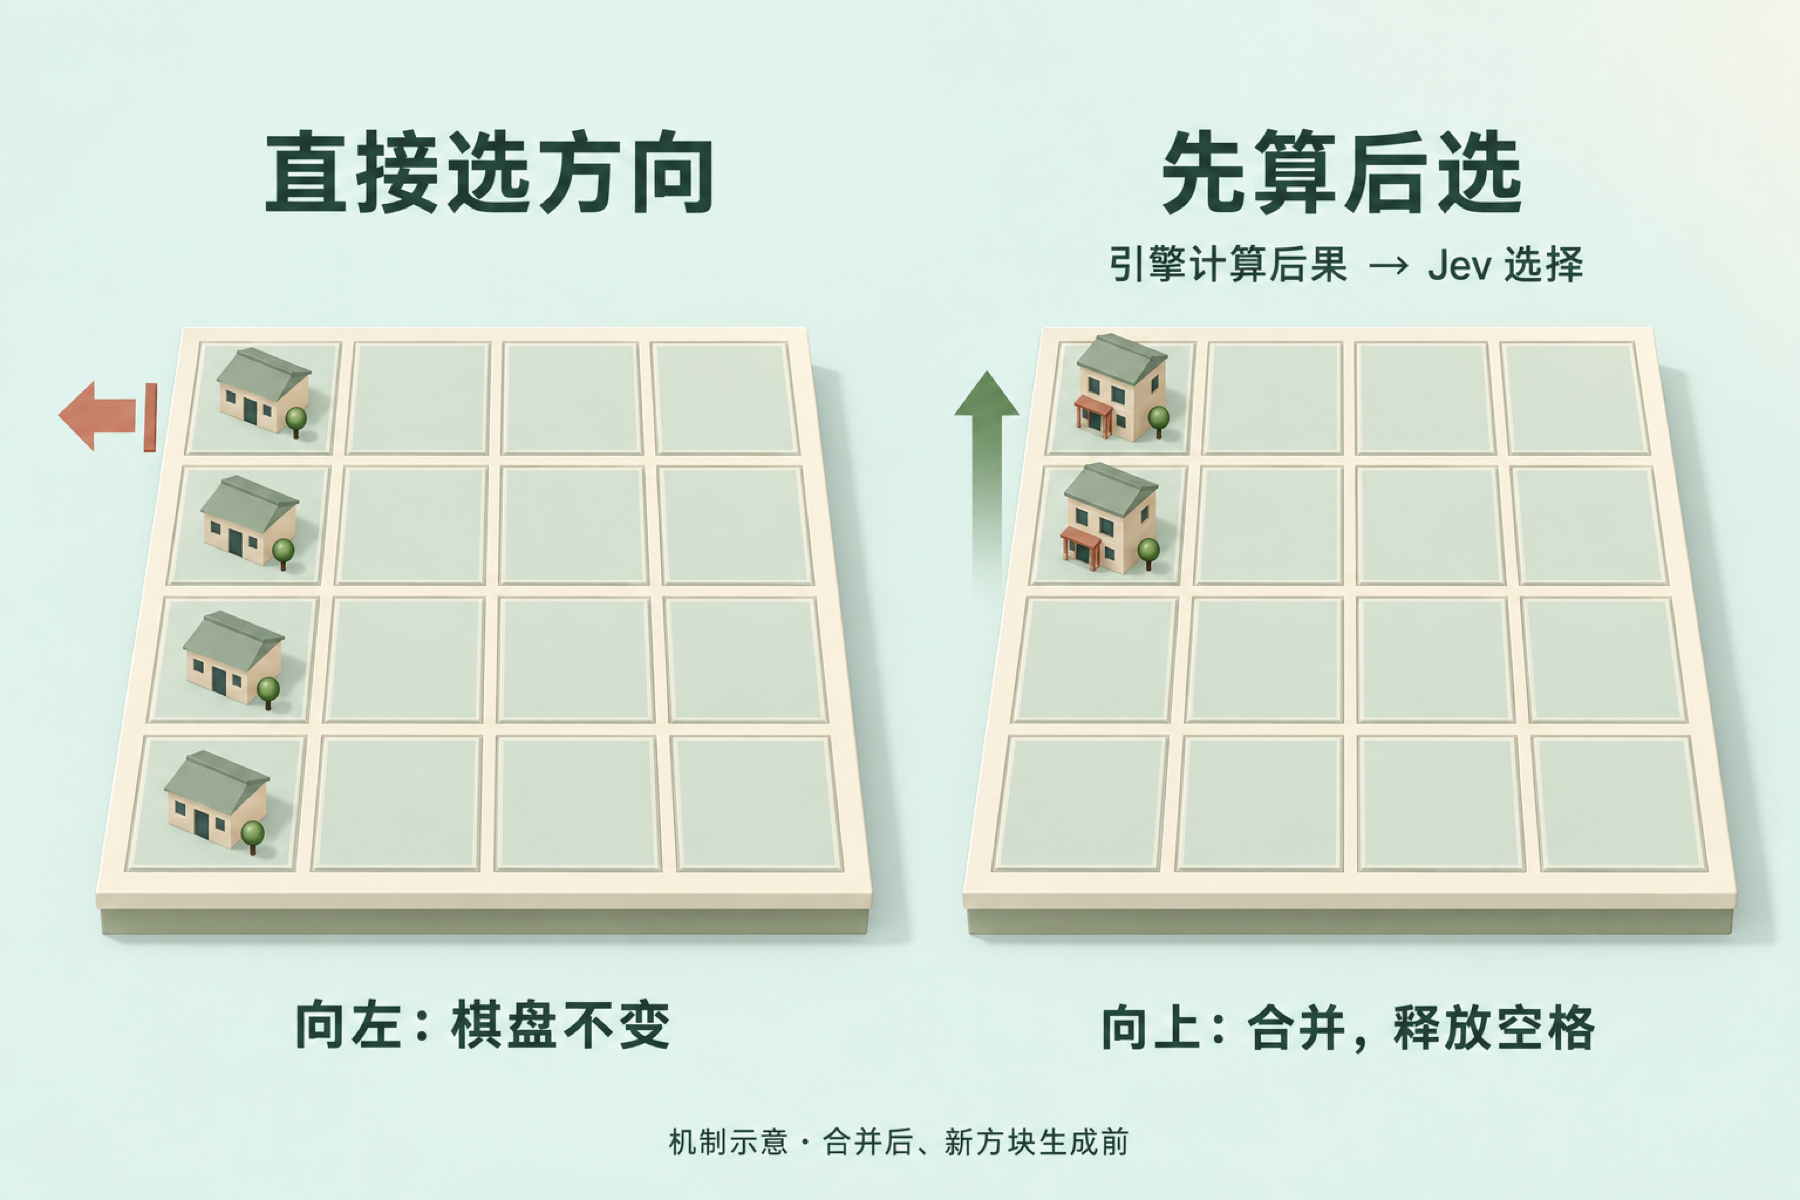
Diagram: Direct selection can choose invalid moves; supplying engine-computed outcomes allows Jev to select valid, score-optimizing actions.
Removing move simulation from the model's workload yielded striking results:
| Strategy | Score | Largest tile | Invalid moves | Chose reference favorite |
|---|---|---|---|---|
Jev, rules |
1,312 | 128 | 26.8% | 24.6% |
Jev, preview |
5,116 | 512 | 0.0% | 29.5% |
Luna-low, rules |
2,800 | 256 | 0.4% | 50.0% |
Luna-low, preview |
2,304 | 256 | 0.0% | 32.1% |
Providing pre-computed move outcomes caused Jev's score to jump from 1,312 to 5,116 while eliminating invalid moves (0.0%). Conversely, Luna's score dropped slightly (2,800 to 2,304), likely because greedy engine heuristics interfered with its internal reasoning.
Caution: The 5,116 score reflects engine assistance. Since invalid moves were explicitly labeled in the prompt, Jev's improvement stems from engine-provided data rather than autonomous board evaluation.
These probes demonstrate that Jev's primary limitation in CityMaker was not action selection among known outcomes, but rather evaluating board states and deriving move consequences independently.
6. Speed and cost: fast, but speed did not become points
Jev achieved median decision latencies of 349–362ms, consuming ~900 input tokens per move in minimal-rules mode. Standard LLMs required 5–12 seconds (p95 latency up to 41s) and 78k–737k thinking tokens per game.
At TypeSafe's pricing ($0.042 per million input tokens, free output), 900 input tokens cost ~$0.00004 per decision, or ~$0.015 for a 400-move game.
While Jev is exceptionally fast and inexpensive, its speed advantage did not translate into higher scores, larger tiles, or valid gameplay.
7. Final thoughts
Jev is marketed as a "System One" model, but thinking tokens exist for a reason. Spending compute to evaluate and verify intermediate decisions yields tangible performance gains. If removing internal reasoning compromises action evaluation, raw speed becomes counterproductive.
TypeSafe emphasizes type safety: Jev outputs structured JSON rather than unstructured text, ensuring reliable parsing. This is a solid engineering feature that eliminates syntax parsing errors.
However, type safety guarantees structural validity, not semantic accuracy. A structurally flawless wrong answer is still wrong.
In complex decision environments, accuracy and reasoning ("System Two") remain paramount. Speed is valuable only when built on a foundation of reliability. A fast response is no substitute for a correct one.
Special thanks to Enkira.ai (founded by my university classmate) for supporting this benchmark evaluation 🎉. The lab is building AI agents designed to master real-world business logic rather than engaging in conversational small talk.